Edge AI vs Cloud AI: Key Differences and How to Decide
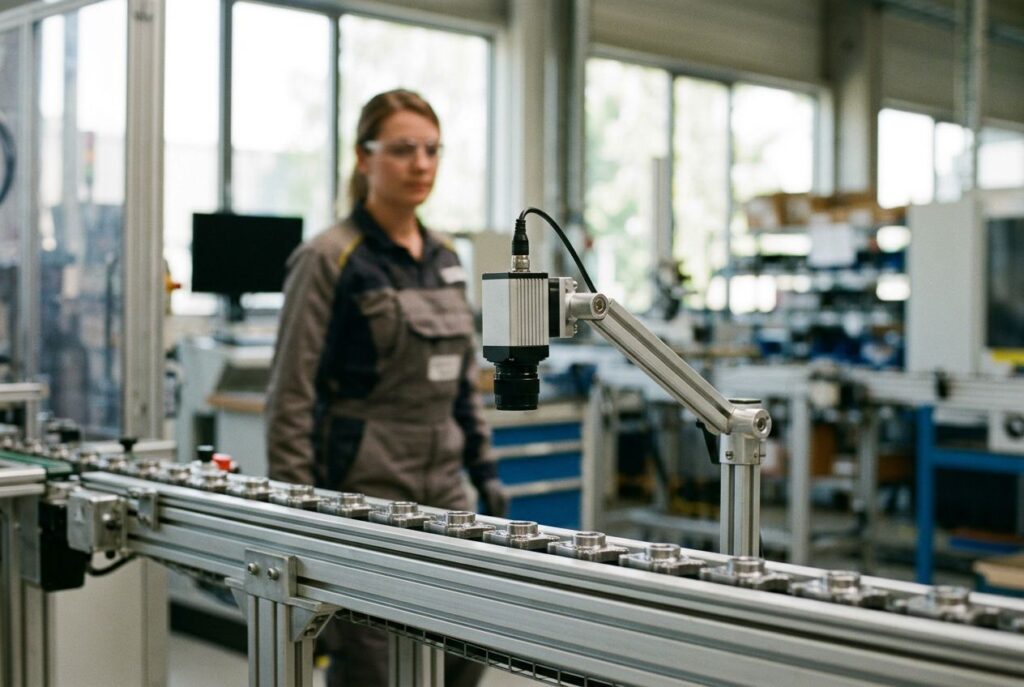
Edge AI runs a trained model on the device where the data is created — a camera, a sensor, a phone, a factory controller — while cloud AI ships that data to a remote data center and sends the answer back. The two approaches can run the exact same neural network; the difference is where the round trip happens, how much raw data has to travel, who can see it along the way, and who pays for the compute. This guide walks through the trade-offs that actually decide the question — latency, privacy, cost, and bandwidth — shows where each approach (and the hybrid pattern that combines them) gets used in practice, and ends with a practical framework for choosing.
What is edge AI?
Edge AI means running inference — the act of using an already-trained model to produce an answer — on hardware physically close to where the data originates, instead of sending that data to a centralized facility. As NVIDIA's engineering blog frames it, the computation happens near the user, at the edge of the network, rather than in a centralized cloud facility or private data center. The "edge" can be almost anywhere: a retail store, a hospital room, a drone, a car, or a traffic light.
Edge AI still depends on a two-stage pipeline: training — teaching a neural network by showing it large volumes of labeled examples — is compute-hungry and typically happens in a data center or the cloud. Once trained, the model becomes a much lighter "inference engine" that can answer real-world questions on the spot, and it is that inference engine, not the training process, that gets deployed to the edge device. When an edge model encounters something it handles poorly, the troublesome data is often uploaded back to the cloud to retrain the model, which eventually replaces the inference engine running in the field — a feedback loop that keeps edge deployments improving over time.
What is cloud AI?
Cloud AI keeps the inference engine centralized. Devices in the field capture raw data — video frames, audio, sensor readings, text — and send it over a network to servers run by a cloud provider, where the model runs and a response comes back. As Coursera's overview of the two approaches puts it, cloud AI runs on servers hosted by providers such as Google Cloud, AWS, or Microsoft Azure, giving organizations access to large datasets and heavy compute without the expense of building that infrastructure themselves. Teams that need that compute for their own training runs typically rent it rather than buy it, whether from a hyperscaler or from a specialized cloud GPU provider.
Because the model lives in one place, cloud AI is easy to update — push a new version once and every request benefits immediately — and easy to scale by adding instances behind a load balancer. That makes it a good fit for workloads that are not latency-critical: batch analytics, document processing, and anything where a response measured in hundreds of milliseconds to a few seconds is fine.
Key differences: latency, privacy, cost, and bandwidth
Four factors decide which approach fits a given workload, and they tend to move together rather than independently.
Latency
Edge inference happens on the device, so the only delay is local compute time. Cloud inference adds a network round trip on top of that — the request has to reach the data center, get processed, and come back — and that round trip is subject to the physical limits of signal propagation and to network congestion, neither of which the application controls. For tasks with a hard real-time requirement, such as an autonomous vehicle deciding whether to brake or a factory robot avoiding a collision, that round trip is the deciding factor regardless of how fast the cloud's servers are.
Privacy and data sovereignty
Edge AI can analyze sensitive data — a face, a voice, a medical image — without ever transmitting the raw data off the device; only the resulting insight, or nothing at all, needs to leave. Cloud AI requires that raw data to be transmitted somewhere else, which is a real exposure surface and a compliance question in regulated industries, even when the transmission itself is encrypted.
Cost and bandwidth
Edge deployments carry an upfront hardware cost per device but keep ongoing network and cloud-compute charges low, because only compact results — an alert, a label, a count — travel back, not the raw stream. Cloud deployments avoid that hardware capex and price on a pay-as-you-go basis, but every raw frame, sample, or reading has to be transmitted, which is where bandwidth cost accumulates as the number of devices grows. Neither model is categorically cheaper; the answer depends on device count, data volume per device, and how often the workload actually runs.
The table below summarizes how the two approaches compare across the factors that matter most in practice.
| Factor | Edge AI | Cloud AI |
|---|---|---|
| Latency | Local compute only — no network round trip | Local compute plus network transit time to and from the data center |
| Data exposure | Raw data can stay on the device; only results need to leave | Raw data is transmitted to a third-party facility for processing |
| Scaling model | Scaling means deploying and updating more physical devices | Scaling means provisioning more cloud instances behind a load balancer |
| Connectivity | Can run offline or on an unreliable link | Requires a working, sufficiently fast connection |
| Cost shape | Upfront hardware per device, lower recurring data-transfer cost | No device hardware, but recurring compute and bandwidth cost that scales with usage |
| Model updates | Pushed to devices individually, or in fleets via device management | Updated centrally; every request uses the latest version immediately |
Hybrid patterns: why most real systems use both
Framing this as a binary choice misses how production systems are actually built. The cloud and the edge play complementary roles across the lifecycle of a model, and there is more than one way to split the work:
- Train in the cloud, infer at the edge. The most common pattern: heavy, data-hungry training runs on cloud GPUs, and the resulting lightweight inference engine ships to devices in the field.
- Retrain from edge feedback. Cases the edge model handles poorly get uploaded — sometimes anonymized — back to the cloud, where the model is retrained and an improved version is redeployed to the fleet.
- Split inference by complexity. A voice assistant can recognize its wake word entirely on-device, then forward only the follow-up request to the cloud for the heavier natural-language processing that a full response requires — the local model acts as a filter, not a complete solution.
- Cloud-managed fleets. The cloud distributes the latest model version and monitors device health across many edge locations at once, even though the inference itself never leaves those devices.
Standards bodies have formalized parts of this pattern for telecom infrastructure specifically: ETSI's Multi-access Edge Computing (MEC) group standardizes how applications from different infrastructure and edge-service vendors interoperate on a shared MEC platform, so that edge compute placed inside mobile and fixed networks behaves predictably regardless of vendor.
Real-world examples
The trade-offs above are abstract until you see where they force a specific architecture:
- Predictive maintenance in manufacturing. Sensors mounted on equipment scan continuously for early signs of failure. Running that analysis at the edge means an anomaly triggers an alert in the moment it appears, instead of waiting for a batch upload — and it avoids streaming a continuous sensor feed to the cloud for a decision that is usually "everything is normal."
- Autonomous vehicles and robotics. A self-driving system that needs to react to a pedestrian cannot wait on a network round trip, so perception — combining data from cameras, LiDAR, and radar through a sensor fusion pipeline — runs on compute inside the vehicle itself; route planning and fleet analytics, which are not time-critical in the same way, can run in the cloud.
- Ultra-low-latency surgical video. Medical instruments increasingly stream and analyze surgical video locally so a minimally invasive procedure gets insight in real time, rather than depending on a network connection during an operation.
- Smart speakers and voice assistants. Wake-word detection ("Hey Siri," "OK Google") runs on-device for both speed and privacy, so the microphone is not effectively always streaming to the cloud; once the wake word triggers, the actual request is typically sent out for cloud-based processing.
- Chatbots, business intelligence, and generative AI. These workloads are the mirror image: they need large models and large context windows, tolerate a second or two of latency, and benefit from being updated centrally, so they run in the cloud almost by default.
How to decide: a practical framework
Four questions, asked in this order, resolve most edge-vs-cloud decisions:
- Does the task have a hard real-time deadline? If a decision has to happen within milliseconds — collision avoidance, industrial safety interlocks — that alone rules out a cloud round trip for that specific decision, even if other parts of the same system run in the cloud.
- Does the data need to stay local? Regulatory or contractual requirements around health, biometric, or proprietary industrial data can make on-device processing the only compliant option, independent of latency.
- What does the data volume look like at scale? One camera streaming continuously is a rounding error; a thousand cameras streaming continuously is a bandwidth and egress-cost problem that edge pre-processing solves by sending only the alerts and clips that matter.
- Does the workload need to run without a reliable connection? Field equipment, ships, remote installations, and anything that must keep functioning during an outage points toward the edge; anything centrally managed with a stable connection can lean on the cloud.
On the hardware side, "edge AI" today usually means a small board with a dedicated accelerator rather than a general-purpose server. The NVIDIA Jetson Orin Nano is a common choice for vision and robotics workloads that need more headroom than a bare Raspberry Pi provides; for lighter projects, a Raspberry Pi paired with an accelerator HAT is often enough, and it's worth comparing the two platforms directly — see our guide to Raspberry Pi AI HAT+ vs. Jetson — before committing to one. For a broader menu of ready-made options, our roundup of Raspberry Pi AI kits covers current camera- and accelerator-based bundles.
Frequently asked questions about edge AI and cloud AI
Is edge AI better than cloud AI?
Neither is universally better — they solve different problems. Edge AI wins when a task needs an instant, local response or when the data cannot leave the device; cloud AI wins when a task needs heavy compute, large context, or centralized updates and can tolerate the time a network round trip adds. Most production systems that need both simply use both.
What are the downsides of edge AI?
Edge devices have fixed, limited compute and storage that cannot be upgraded the way a cloud instance can be resized, so they generally run smaller, more specialized models than a data center can. Fleets of devices are also harder to update and monitor than a single centralized service, and each device carries its own upfront hardware cost.
How much does edge AI cost?
There is no single figure, because the cost shape is different from cloud AI rather than simply higher or lower: edge AI concentrates cost upfront in hardware purchased per device, then keeps ongoing data-transfer and cloud-compute costs low because only compact results need to be sent anywhere. Cloud AI avoids the device hardware cost entirely but bills continuously for compute and, at scale, for the bandwidth needed to move raw data. Which one is cheaper depends on how many devices are involved and how much data each one produces.
Is edge AI a real, widely used technology, or mostly marketing?
It is already running in production across manufacturing, healthcare, retail, and consumer devices — predictive-maintenance sensors, on-device wake-word detection in smart speakers, and vision systems in vehicles and robots are all edge AI in everyday use, not a future promise.
Can edge AI and cloud AI work together?
Yes, and in most real deployments they do. A common pattern trains the model in the cloud and runs inference at the edge, then periodically sends cases the edge model struggles with back to the cloud for retraining — improving the deployed model over time without moving the day-to-day workload off the device.
What is the difference between edge computing and edge AI?
Edge computing is the broader infrastructure concept: processing any kind of workload physically close to where data is generated instead of in a centralized data center. Edge AI is a specific application of that idea — running a trained AI model's inference step on that local hardware rather than sending the data to the cloud for the model to process.
Recommended: